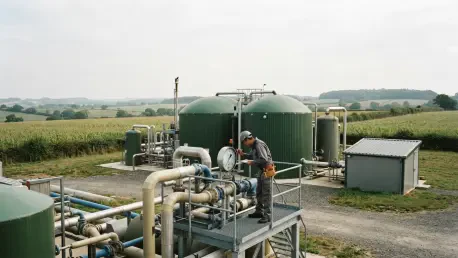
Recent experiments using the ESP32 microcontroller reveal that basic mathematical persistence models often outperform sophisticated neural networks in daily biogas estimation. This realization has fundamentally challenged the prevailing tech-industry assumption that complex artificial intelligence is the universal answer to renewable energy optimization. As decentralized energy production becomes a cornerstone of the circular economy, the focus has shifted toward Edge AI and TinyML as potential tools for democratizing process control. Anaerobic digestion, a biological method used to convert organic waste into methane-rich biogas, is a prime candidate for this technological intervention due to its inherent volatility and the high cost of traditional monitoring equipment. For small-scale agricultural operations, industrial-grade sensors and SCADA systems remain financially out of reach, creating a massive barrier to efficient resource management. By implementing ultra-compact inference frameworks on budget-friendly microchips like the ESP32, developers aimed to provide low-cost oversight that could scale to rural settings. However, the unique intersection of digital precision and slow-moving biological processes has exposed a significant gap between computational capability and actual predictive utility. This development is forcing a necessary pivot in how the industry approaches the smart automation of living systems, moving away from hype and toward grounded biological reality.
The Dominant Influence of Biological Process Inertia
A fundamental realization in biogas modeling is the concept of biological memory, which governs the steady state of a reactor. In mesophilic systems, the hydraulic retention time typically spans between 15 and 25 days, meaning the material processed today is the result of microbial work that began weeks ago. Because the biochemical conversion of organic matter into methane is a slow, multi-stage journey, today’s gas production is rarely a sudden reaction to immediate chemical fluctuations. Instead, the process is characterized by heavy inertia, where the reactor’s current state is inextricably linked to its historical performance. This slow-moving nature acts as a natural buffer, smoothing out the impact of minor operational changes and making the system resistant to rapid shifts. For modeling purposes, this implies that the most significant driver of today’s output is not a complex web of recent chemical sensor readings, but rather the simple momentum of the biological population itself.
Statistical analysis of these systems confirms that historical production data holds a dominant Pearson correlation of 0.847 with current output. This overwhelming reliance on what happened yesterday creates a unique challenge for machine learning developers who are accustomed to datasets where features provide distinct, predictive signals. When a single historical variable carries such massive weight, the added intelligence of a complex neural network often struggles to provide any value beyond what a simple persistence model already offers. In many cases, the high correlation between consecutive days of production means that any sophisticated algorithm is essentially attempting to predict a value that is already known. This dominance of process inertia suggests that for stable anaerobic digesters, the biological state is its own best predictor, rendering many advanced data science techniques redundant for routine daily forecasting.
Comparing Machine Learning to Simple Statistical Baselines
The effectiveness of TinyML in an agricultural context is often judged by its ability to outperform elementary statistical methods. In recent testing, a custom-trained multilayer perceptron (MLP) was pitted against a persistence baseline and linear autoregression to see if neural networks could offer a competitive edge. Surprisingly, the complex neural network failed to achieve superior results, highlighting a disconnect between model sophistication and practical accuracy. While the persistence model maintained a coefficient of determination of 0.572, the specialized neural network only reached 0.343. This discrepancy suggests that the neural network was essentially processing noise rather than identifying deeper biological patterns. For operators looking for reliable data, the simplest approach—assuming today will be exactly like yesterday—provided a much more accurate representation of reality than the multi-layered digital brain.
This performance gap underscores a critical lesson in right-sizing technology for the agricultural sector. Just because a sophisticated model can be deployed on a low-cost microcontroller does not necessarily mean it is the most effective tool for the task at hand. In stable biological environments, the underlying physics and slow reaction times favor simpler solutions that are easier to validate and maintain. For many decentralized energy projects, the perceived intelligence of artificial intelligence may be an unnecessary layer of complexity when compared to the straightforward reliability of historical trend monitoring. By focusing too heavily on the power of the algorithm, researchers may overlook the fact that the most valuable information is often found in the most basic observations. This finding encourages a more pragmatic approach to Edge AI, where the choice of model is driven by the specific dynamics of the biological process rather than a desire for technical complexity.
Validation Rigor and the Rolling-Origin Evaluation Protocol
Many academic claims regarding artificial intelligence accuracy in agriculture are criticized for being overly optimistic due to flawed validation techniques. Standard practices, such as random cross-validation or single train-test splits, often ignore the temporal nature of biological data, leading to a phenomenon known as data leakage. This occurs when a model inadvertently learns from information it should not have access to in a real-world scenario, such as using future data points to predict past events. To combat this, researchers have begun championing the rolling-origin evaluation protocol, which tests the model sequentially as it would function in a real-time environment. This rigorous method ensures that the model is only ever looking at the past to predict the future, providing a much more honest assessment of its utility in the field.
This rigorous approach demonstrates that models appearing highly accurate on static datasets often fail to generalize when applied to subsequent time periods. By testing the model across multiple windows of time, the research proved that temporal benchmarking is a non-negotiable requirement for biological modeling. Without this level of rigor, practitioners risk deploying smart systems that are incapable of handling the gradual shifts and seasonal changes inherent in real-world farming. The failure of complex models to hold their accuracy over time reveals that what was once thought to be learning was often just overfitting to a specific, narrow slice of history. As the industry moves toward more robust decentralized monitoring, the adoption of strict temporal validation will be essential for distinguishing between genuine predictive power and statistical mirages.
Technical Success in Hardware Efficiency and Firmware Profiling
Despite the predictive limitations of the neural network in this specific case, the mechanical feasibility of the ESP32 platform was a resounding success. Engineers successfully converted the neural network into a C++ header file and flashed it onto the chip, proving that the hardware is more than capable of handling complex mathematical inferences at the edge. The entire inference cycle—including the necessary data normalization and denormalization steps—was executed in a mere 48.899 microseconds. This level of speed is far beyond what is required for biological monitoring, where changes happen over hours rather than milliseconds. It confirms that the current generation of low-cost microcontrollers can easily host sophisticated models without the need for cloud connectivity or expensive high-end processors.
The resource efficiency of the ESP32 is equally impressive, with the tested model consuming only 1,348 bytes of static storage. This represents less than 0.5% of the available RAM, leaving plenty of room for additional tasks like sensor management, wireless communication, and local data logging. Furthermore, the mathematical output of the microcontroller matched the desktop version with a negligible error margin, ensuring that no accuracy was lost during the transition to the edge. This confirms that the primary bottleneck for smart biogas systems is not the computing power of the microchips, but rather the predictive value of the data being fed into them. We have reached a point where the hardware is ready and waiting for better biological insights, offering a powerful and inexpensive foundation for future decentralized energy technology.
The Persistent Challenge of Model Transferability Across Sites
One of the greatest hurdles for artificial intelligence in the biogas sector is the lack of plug-and-play capability. When research teams attempted to apply their laboratory-trained models to real farm-scale biodigesters, the results were consistently poor. This negative transfer occurs because every biogas reactor is its own unique ecosystem, shaped by specific local feedstocks, microbial communities, and temperature profiles. A model trained on a controlled pilot dataset cannot easily interpret the messy and fluctuating realities of a different site. This means that a neural network that works perfectly in a university lab may be completely useless when installed on a dairy farm just a few miles away.
This site-specific nature means that models must be retrained for every individual installation to be truly effective, which presents a significant barrier for rural farmers. The necessity of a personalized data-gathering period and expert retraining creates a logistical and financial burden that many small operations cannot sustain. Until transfer learning techniques improve or more generalized biological models are developed, the dream of a universal, AI-powered biogas monitor remains difficult to achieve. This highlights the need for research into more adaptable algorithms that can learn the specific characteristics of a new environment without requiring a total overhaul of the system. For now, the biological uniqueness of each reactor remains a formidable opponent for the standardization of Edge AI solutions.
Practical Economic Strategies and Future Implementation
For small-scale farmers looking to optimize their energy production, the findings of recent studies offered practical financial guidance. Given that chemical sensors for pH, ammonia, and acetate were found to be expensive and often provided little predictive signal for daily volume, a more pragmatic investment strategy was recommended. Researchers suggested that most rural operators would benefit more from a high-quality, low-cost gas flow meter than from high-end chemical analysis or complex AI software. The economic reality showed that for a stable reactor, the best predictor of today’s gas remained yesterday’s gas, meaning that reliable physical measurement tools provided immediate, actionable data without the overhead of maintaining sophisticated digital models.
The study concluded that the focus of decentralized AI needed to shift from routine forecasting to the identification of critical system failures. While the experiments demonstrated that simple persistence models provided more reliable daily data, the potential for machine learning to act as an advanced smoke detector for biological crashes remained a promising avenue for future development. Industry experts recommended that rural operators prioritize investments in high-quality physical instrumentation rather than complex chemical analysis software. By grounding future technological advancements in the fundamental physics and biological inertia of the digestion process, the sector aimed to create more resilient and practical monitoring solutions. Ultimately, the successful deployment of TinyML was viewed as a supplementary layer of safety that could predict rare catastrophic shutdowns. Moving forward, the research suggested that developers should concentrate on building generalized models capable of detecting anomalies across diverse sites, thereby reducing the need for costly retraining.